Google rolls out Gemini Omni 1.2 Flash with 15-second video and lower pricing
Matthias Bastian ·
Google DeepMind made Gemini Omni 1.2 Flash generally available with 15-second clips, conversational editing and lower pricing.
Google DeepMind is making its Gemini Omni 1.2 Flash video-generation model generally available, with clips up to 15 seconds long, conversational editing and a 30 percent price reduction, according to The Decoder’s report on Google’s announcement.
The model supports clips between three and 15 seconds, up from a previous maximum of 10 seconds. Pricing for 720p video falls to $0.07 per second. Google says the rollout spans the Gemini API, Google AI Studio, the Google Cloud Console, Flow, Google Vids, the Gemini app for Google AI Ultra subscribers, and Google Ads. Every generated video carries an imperceptible SynthID watermark indicating its origin.
Conversational editing lets users adjust a generated clip through successive requests, changing elements such as the background, lighting or aspect ratio without regenerating the entire clip. According to Google, the feature works across the full 15-second duration.
The company describes a tiered workflow intended to reduce production costs: create drafts at 360p or 720p, correct individual details through follow-up edits, then upscale only the final result to 1080p or 4K. The reported $0.07-per-second price applies specifically to 720p video; the supplied report does not provide pricing for other resolutions or editing operations.
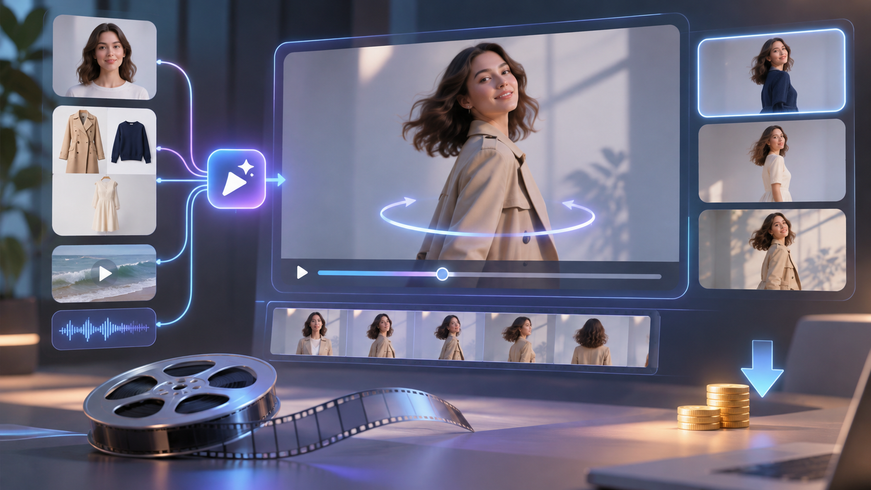
Google also claims improved adherence to reference material. Supported inputs include character images, product photos, motion clips of up to three seconds, and audio cues. The company says the model better preserves faces, clothing, packaging typography and brand colors across camera angles.
In one example described by The Decoder, Google demonstrates a virtual try-on sequence generated from a single model photo and product shots of three outfits. The 15-second clip includes 360-degree turns while, according to Google, preserving the model’s identity and the garments’ cut and drape.
Other claimed improvements include reduced visual drift and morphing during motion and camera transitions, more natural-sounding dialogue, clearer lip-sync and better distinction between multiple speakers. Google also says the model handles continuous camera movements, including FPV drone flights and dramatic zoom-outs, with fewer unwanted jump cuts.
These quality improvements are Google’s claims as reported by The Decoder. The supplied material does not include independent testing or quantitative benchmarks to establish their extent.
Routing Brief Privacy Policy
Routing Brief is operated by JavaRouter AI Inc., a company registered in the United States. This Privacy Policy describes personal information handled through our English-language AI media website, rankings, newsletters and related services. An account, paid plan, API or app feature described below applies only if we actually offer it and you use it.
Last updated: October 9, 2026. This policy is a notice of our practices; reading it or browsing the website does not, by itself, provide consent for optional cookies, marketing or any processing that requires separate consent.
1. Information we collect
Information you provide
Accounts and support: email address, authentication details, support messages and information you choose to include in a request. If you choose third-party sign-in, we receive the information authorized by that service.
Profiles and contributions: a display name, avatar, submissions, comments or corrections, where those features are available. Public contributions may be visible to other readers.
Newsletters and alerts: your delivery address, subscription choices, confirmation status and unsubscribe preferences. Optional notifications require the relevant opt-in or device permission.
Payments, if offered: plan, billing contact, transaction, renewal, cancellation and invoice records. Payment providers process payment credentials under their own notices; do not send card details in a support message.
Developer access, if offered: account identifiers, access entitlements, usage and security logs needed to operate the API. Secret keys must not be included in public posts or support attachments.
Technical and usage information
When the hosted site is accessed, the hosting and security services may process an IP address, browser and device characteristics, requested URLs, approximate region inferred from IP, timestamps, referring pages and error logs. Optional analytics may measure reading, search, clicks and interactions only after the applicable preference is enabled. The local HTML prototype does not send a newsletter subscription or load analytics and advertising trackers.
We may store settings and user-requested features, such as saved articles, locally on your device. We do not request contacts, clipboard contents, microphone audio, precise location or camera access for ordinary website reading. Any future app permission will be requested separately when needed.
2. Purposes and applicable law
We use information to deliver requested content and subscriptions, authenticate accounts, respond to messages, manage payments where offered, maintain security, troubleshoot problems, improve the service and comply with legal obligations. Optional analytics, personalization and advertising are subject to the choices explained below.
Our U.S. operations are subject to applicable federal and state law. State privacy statutes, including the California Consumer Privacy Act as amended by the CPRA and the Delaware Personal Data Privacy Act, apply where their jurisdictional, coverage and threshold requirements are met. Incorporation in the United States does not remove protections that mandatorily apply to readers elsewhere.
If the EU GDPR or UK GDPR applies to particular processing, we identify an appropriate legal basis: contract for requested services, legitimate interests for proportionate security and operations, legal obligation where required, and consent where required for optional processing. These are not presented as a single U.S. legal-basis framework. We will provide additional notice and obtain consent when required before materially incompatible uses.
3. Cookies and similar technologies
Use at any time to review or withdraw choices. The preference center offers equally prominent Accept all, Reject non-essential and Customize controls. Scrolling, closing the banner, or continuing to read does not enable optional categories.
Strictly necessary: security, session functions and remembering your privacy choice. The prototype saves only a first-party preference record for 180 days; local administrative records are created when you use its editor controls.
Functional: optional convenience features and third-party media. Off until selected.
Analytics: optional audience and interaction measurement. Off until selected.
Marketing: optional advertising measurement, retargeting and cross-context advertising technologies. Off until selected.
The prototype has no optional cookie vendors or advertising pixels installed. Selecting a category does not itself add a tracker. Before deploying any vendor, we must disclose its identity, purposes and storage duration and connect it to the relevant consent gate. We do not claim that Cookiebot or another third-party consent platform is installed here.
Token prices: models.dev. Optional benchmarks from Artificial Analysis appear only when data is available. Missing metrics are hidden, not estimated. Source terms apply.
The current prototype does not sell personal information, share it for cross-context behavioral advertising, or use it for targeted advertising. If the hosted service introduces practices that meet those definitions, we will first update the notice, provide the required opt-outs and honor applicable preference signals. A local browser choice does not verify an account-wide request; contact us for account-related rights.
4. Sharing and disclosure
We may disclose information to service providers performing hosting, email delivery, support, security, analytics with the applicable choice, and payments where offered. Their access must be limited to authorized purposes and governed by appropriate agreements. We may disclose information when lawfully required, to protect rights and safety, at your direction, or as part of a merger or asset transfer with appropriate safeguards and notice.
Token prices: models.dev. Optional benchmarks from Artificial Analysis appear only when data is available. Missing metrics are hidden, not estimated. Source terms apply.
5. Your choices and privacy rights
Depending on your location, the law that applies and applicable exceptions, you may request access or confirmation of processing, a portable copy, correction or deletion. You may also have rights to opt out of sale, sharing, targeted advertising or profiling used for decisions producing legal or similarly significant effects, limit certain uses of sensitive information, use an authorized agent, and appeal a denied request. Routing Brief does not use this prototype for such consequential profiling.
California residents have the applicable CCPA rights to know, delete, correct, opt out of sale or sharing, limit qualifying uses of sensitive information, and receive non-discriminatory treatment. This section does not imply that every state law applies to every request. We do not require an account solely to exercise applicable rights.
Send requests to support@routingbrief.com. We may ask for information reasonably necessary to verify access, correction or deletion requests, but not more than needed. Opt-out preference signals do not require identity verification. Authorized agents may need to provide evidence of authority as allowed by law.
Where the applicable U.S. state law provides a 45-calendar-day response period, we respond within that period and give notice of any permitted extension. Opt-outs and other requests may have shorter deadlines and are handled within the applicable limit. Where GDPR applies, its response deadlines apply instead. We explain denials and any applicable appeal process. To appeal, reply with “Privacy Appeal”; we respond within the deadline set by applicable law and identify the relevant regulator where required.
You can unsubscribe using the link in a newsletter or by contacting us. We retain a limited suppression record to respect that choice. You may also contact your state attorney general, the applicable state privacy regulator or the Federal Trade Commission. If mandatory EEA or UK protections apply, rights to complain to the relevant data protection authority remain available.
6. Retention and international processing
We retain information only for as long as reasonably necessary for the disclosed purpose, security, legitimate recordkeeping or legal requirements. Relevant criteria include whether an account or subscription remains active, the nature of a request, statutory retention duties and dispute requirements. Information no longer needed is deleted or de-identified where appropriate; de-identified information will not be re-identified except where law permits.
JavaRouter AI Inc. operates from the United States, and service providers may process information there or in other locations. We do not claim that all information is hosted in the United Kingdom or solely in any single country. Where regulated international transfers occur, we use the applicable transfer mechanism and safeguards. Corporate registration is not proof of a data-hosting location.
7. Security and incident notices
We use reasonable administrative, technical and organizational safeguards appropriate to the information and risks. No system is perfectly secure. Please report suspected compromise and avoid disclosing credentials or sensitive information in public contributions.
If a security incident triggers a notification duty, we notify affected individuals, regulators and other required parties within the periods required by applicable law. We do not impose the UK GDPR’s 72-hour regulatory deadline as a universal U.S. rule.
8. Children and eligibility
The Services are intended for adults aged 18 or older, consistent with the Terms of Service. They are not directed to children under 13, and we do not knowingly collect their personal information. If we learn that information was collected from a child contrary to applicable law, including COPPA where applicable, we take appropriate steps to delete it. A parent or guardian may contact us at the address below. A child’s use of the site is not parental consent.
9. Third-party services and future features
External websites, identity providers, payment providers and social platforms have their own practices. Review their notices before using them. This policy does not state that an account system, native app, paid membership, recommendation engine or specific SDK is currently deployed merely because it describes how such a feature would be handled.
Content categories and rankings are not an individually personalized feed. If personalization is introduced, we will explain the data and choices before activation. Any supplemental notice applies only to the service it describes, subject to mandatory law.
10. Changes
We update the date when this notice changes and give prominent notice of material changes as appropriate. When law requires renewed consent, we request it before the affected processing starts. Continued browsing is not a substitute for that consent.
11. Contact
JavaRouter AI Inc. 8 The Green Ste R, Dover, DE 19901, United States Email: support@routingbrief.com
Routing Brief Terms of Service
These Terms govern Routing Brief, the AI media website and related services operated by JavaRouter AI Inc., a company registered in the United States. They apply to AI news, model pricing and rankings, engineering guides and newsletters. Additional account, paid subscription, community, API or app terms apply only where those services are offered.
Last updated: October 9, 2026.
1. Eligibility and agreement
The Services are intended for adults aged 18 or older who have the legal capacity to enter this agreement. By affirmatively accepting these Terms, or using the Services after reasonable notice of them, you agree to them to the extent enforceable under applicable law. We use a separate affirmative acceptance step for an account or purchase when appropriate. A privacy notice is not consent to optional tracking.
If you use the Services on behalf of an organization, you represent that you have authority to bind it. If you disagree with these Terms, stop using the Services. Mandatory consumer rights remain in force.
2. Service scope and permitted use
Routing Brief provides information about AI models, applications, infrastructure and industry developments. We grant you a limited, non-exclusive, non-transferable permission to access the Services for personal use or internal business evaluation, subject to these Terms. These Terms do not prevent uses permitted by copyright law or a separate open license.
We may improve, update or discontinue features. We will give notice and honor applicable obligations where a change materially affects a paid service. Use official channels to obtain any software we release; no native app is implied by this agreement.
3. Accounts and paid services
If accounts are available, provide accurate registration information, safeguard credentials and promptly notify us of suspected compromise. Do not impersonate others or sell or transfer an account without permission. You are responsible for activity you authorize; you are not automatically responsible for every unauthorized action regardless of fault.
If paid subscriptions are offered, checkout and the applicable Subscription Terms must disclose price, billing interval, renewal, cancellation and refund conditions before purchase. Recurring billing requires the applicable informed consent. Cancellation and refunds are subject to those disclosed terms and mandatory federal and state consumer laws. These general Terms alone do not authorize any charge.
4. Acceptable use and contributions
Do not use the Services to commit fraud, threaten or harass people, distribute malware, infringe privacy or intellectual property, impersonate another person, spam users, bypass access controls, or materially disrupt the service. Do not obtain non-public information or circumvent a paywall or rate limit without permission. Restrictions apply only to the extent permitted by law, including applicable exceptions for lawful security research and interoperability.
Where submissions or comments are enabled, you retain your ownership and grant us a non-exclusive license to host, reproduce, format and display the content as necessary to operate and promote the relevant service. You must have the rights needed to submit it. Attribution to a source does not by itself grant republication permission.
We may moderate content or restrict access for material violations or security reasons. Where practicable and legally appropriate, we give notice and a reason. You may request review through support@routingbrief.com. We consider appeals in good faith. Nothing requires you to compensate us for our own unlawful conduct.
5. Privacy and communications
The Privacy Policy describes information practices and applicable rights. Optional cookies can be managed through . Required service communications are distinct from optional newsletters and marketing. Marketing emails include an unsubscribe method and must comply with applicable law, including CAN-SPAM when applicable.
6. Rankings and informational content
Token prices: models.dev. Optional benchmarks from Artificial Analysis appear only when data is available. Missing metrics are hidden, not estimated. Source terms apply.
Token prices: models.dev. Optional benchmarks from Artificial Analysis appear only when data is available. Missing metrics are hidden, not estimated. Source terms apply.
Token prices: models.dev. Optional benchmarks from Artificial Analysis appear only when data is available. Missing metrics are hidden, not estimated. Source terms apply.
Content is for general information and is not individualized financial, investment, legal, tax or other professional advice. A ranking is not a warranty that a model or application suits your workload. Test engineering guidance in an appropriate environment before production use. We correct identified errors through our editorial process.
7. Third parties and sponsorship
Token prices: models.dev. Optional benchmarks from Artificial Analysis appear only when data is available. Missing metrics are hidden, not estimated. Source terms apply.
We disclose paid sponsorship and material commercial relationships. Editorial independence does not mean an absence of ownership or financial relationships. Sponsored material and first-party promotional links must be identified where relevant.
8. Intellectual property and data licenses
JavaRouter AI Inc. or its licensors own the Routing Brief brand, original editorial content and website materials, except where a different owner or license is identified. All rights not expressly granted are reserved, subject to fair use and other statutory exceptions. Do not remove attribution or ownership notices.
Token prices: models.dev. Optional benchmarks from Artificial Analysis appear only when data is available. Missing metrics are hidden, not estimated. Source terms apply.
Send copyright concerns to support@routingbrief.com, identifying the work, disputed URL, your contact details and basis for the request. This contact is not represented as a registered DMCA agent. We will publish any designated-agent details separately if that process is established.
9. Service availability and liability
To the fullest extent permitted by law, the Services are provided “as is” and “as available.” We do not promise uninterrupted access, error-free third-party data or a particular result. You remain responsible for evaluating sources and your implementation decisions.
To the extent permitted by applicable law, we are not liable for indirect, incidental, special or consequential losses caused by reliance on informational content or third-party services. This provision does not exclude liability for fraud, willful misconduct, gross negligence where it cannot lawfully be excluded, or any liability or consumer remedy that cannot be limited by law. We do not create a new monetary liability cap in this version.
10. Governing law and disputes
These Terms and disputes arising from them are governed by the laws of the State of Delaware, without applying its conflict-of-laws rules, and applicable United States federal law. This choice reflects the operator’s Delaware address supplied for this site. It does not remove mandatory protections available under the law of your state or country of residence.
Subject to non-waivable consumer rights and any legally required venue, disputes may be brought in state or federal courts of competent jurisdiction in Delaware, and the parties consent to those courts’ jurisdiction. Consumers retain any right under mandatory law to bring proceedings in their home jurisdiction or in small-claims court where appropriate.
Please contact us first when practicable so we can attempt to resolve a concern in good faith. This request does not delay urgent relief, shorten a limitation period or prevent a complaint to a regulator. These Terms do not add mandatory arbitration or a class-action waiver.
11. Changes, severability and contact
We may revise these Terms and will post the updated date. For changes materially affecting rights, or an increase in fees for paid subscribers, we provide at least 30 days’ advance notice where practicable and required, and allow cancellation before the change takes effect. Changes necessary for security or legal compliance may take effect sooner where law permits. Existing accrued rights are not retroactively removed.
If a provision is unenforceable, the remaining provisions continue to apply to the extent lawful. A failure to enforce a provision is not a waiver. Headings aid navigation and do not alter meaning.
JavaRouter AI Inc. 8 The Green Ste R, Dover, DE 19901, United States Email: support@routingbrief.com
Your privacy, your choice
We use necessary storage to remember your choices. Optional functionality, analytics and marketing stay off unless you choose them. Privacy Policy
Global Privacy Control is on. Marketing remains off.
Model Index · AI Routing & independent evals
AI Model Leaderboard
Scores combine AI Routing measurements with results from independent third-party evaluators, normalized to a single scale and weighted by domain.
Token prices: models.dev. Benchmarks: Artificial Analysis. Intelligence, coding, agentic and output speed are distinct metrics; no usage or market-share statistics are inferred.
Prices are USD per million tokens. The 3:1 blend is illustrative. Missing metrics are unavailable, never zero. Benchmark fetch timestamps are not evaluation dates. API index versions are displayed when supplied.
API and attribution
Benchmark requests use the free server-side endpoint, refresh at most hourly, and retain the last successful local snapshot. API keys are never sent to the browser. Data is subject to Artificial Analysis terms and the applicable subscription; attribution does not grant redistribution rights. No historical sample scores are substituted on failure.
Corrections
Send the category, affected row, source and proposed correction to support@routingbrief.com. Preserve source provenance when correcting a snapshot. Browser-local admin changes in the prototype are not audited production updates.
Routing Brief admin
Risk control · Manual override layer
Model Index data
The index updates automatically. This page is the fallback for when an update is wrong: edits here are stored in your browser and layered over the shipped data, so a bad collector run can be corrected in seconds without a deploy. Nothing here is published to other visitors.
Redundancy by design. Shipped data is never mutated — overrides live beside it in localStorage under rb.modelIndex.overrides.v1. Reverting a field or the whole table restores the collector’s value immediately, so there is no state you can reach from here that you cannot get back out of.
Models tracked—
Fields overridden—
Rows touched—
Snapshot dates—
Snapshot metadata
Shown on every public table. Correct these if a run stamped the wrong time or cadence.
Models
Edit a cell and it saves on blur. Yellow means overridden. Every field the public boards read is editable here. Saving, Blended, Score / $, Spread and Share are absent on purpose — they are computed from these columns at render time, and a stored figure that contradicts the numbers beside it would be worse than none.
Model
In / 1M
Out / 1M
List / 1M
Saving
p50 ms
p99 ms
Tok/s
Uptime
24h %
Score
Tool
Context (K)
Tokens (T)
Apps
Status
Agent handoff: the ai-news-radar pipeline writes data/model-index-delta.json and never edits assets/models.js. Import that file above to review its proposed numbers before they reach the public tables.
Routing Brief admin
Editorial queue · AI News & Guides
Articles
The ai-news-radar agent finds, filters and re-writes candidates, then drops them here as drafts. Your job is review and publish. Reprints cannot leave the queue until their attribution and summary are filled in.
Copyright rules are enforced, not suggested. Anything marked Reprint needs the source publication and the original author before it can be published. News reprints additionally need a one-sentence summary of the whole piece, which is rendered as the first line of the article. Publish stays disabled until both are present.
Drafts—
In review—
Published—
Blocked on attribution—
Nothing matches this filter.
Agent handoff: ai-news-radar writes candidate entries to drafts/ as JSON with the same field names used here, including origin, sourceName, sourceAuthor and summary. Import them above. The queue lives in localStorage under rb.articles.v1; export before clearing browser data.
 Routing Brief admin