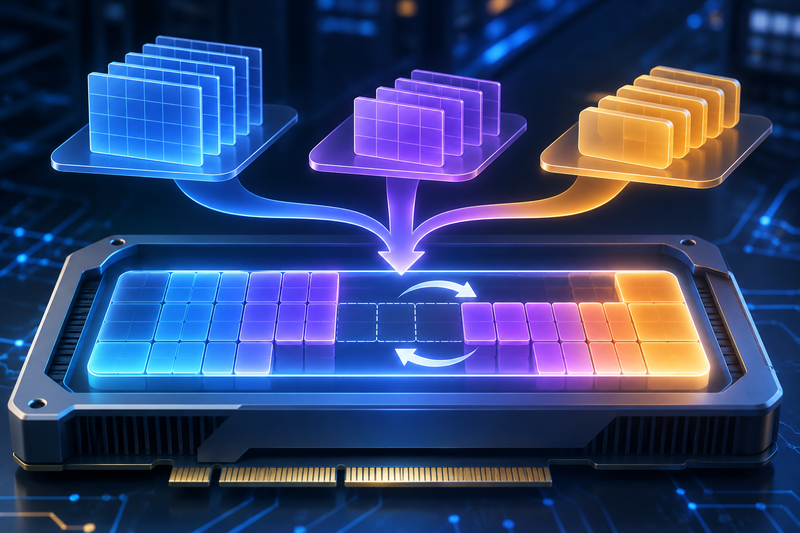
SGLang’s experimental unified memory lets hybrid models share GPU capacity across KV caches and recurrent state.
In a technical post, LMSYS describes an opt-in allocator enabled with --enable-unified-memory that replaces fixed memory partitions with one shared GPU arena. The change targets hybrid models whose full-attention caches, sliding-window caches and recurrent states compete for capacity in different ways. Reported benefits vary by workload; the feature remains experimental and has significant compatibility restrictions.
Why the memory split matters
Full attention retains the entire context, sliding-window attention retains a bounded suffix, and recurrent layers maintain a fixed-size state for each running request. Their memory requirements therefore respond differently to longer sequences and higher concurrency.
SGLang’s separate-pool design fixes the allocation among these state types at startup. According to the post, that can leave usable memory stranded: a long-context workload may fill its full-attention pool while capacity reserved for bounded state remains idle, while many short requests can create the opposite imbalance.
Unified memory removes those runtime partition boundaries. Full-attention KV grows inward from one end of the arena, while bounded state grows from the other. Compaction moves live allocations so freed capacity becomes available to the state type that needs it. The existing ratio flags remain boot-sizing targets rather than fixed runtime limits.
The practical distinction is between sharing capacity and reducing memory consumption. The design does not eliminate a request’s cache or state requirements. Instead, it aims to let those requirements draw from the same available bytes, reducing the need to predict the workload mix before starting a server.
A layout designed for movement
The post describes a new KV layout that packs a token’s rows across layers into one entry. Allocation, eviction and whole-page relocation can then operate across those layers together. Rows within an entry can retain different shapes and data types, allowing compatible speculative drafts to share allocation and movement with target-model KV.
Each state type still uses its own allocation unit: KV pages need not match the size of recurrent-state slots. The allocator evaluates their combined demand, including page rounding and expected decode allowance, rather than treating free full-attention tokens as a sufficient measure of capacity.
Sharing bytes also makes synchronization important. SGLang records page readers and writers so a logically freed page can count toward capacity without being overwritten while earlier GPU work still uses it. This separates admission accounting from safe physical reuse—a necessary distinction when scheduling overlaps with model execution.
What the reported tests show
LMSYS compared unified memory with separate pools at their default ratios using one H200 per server, SGLang commit daa171846f and averages of two runs.
For Qwen3.5-4B with 1,024 input tokens, 256 output tokens and concurrency 64, unified memory delivered 5,830 output tokens per second versus 5,880 for separate pools. Both scored 0.875 on a 200-question GSM8K evaluation. That result supports broadly similar performance in this configuration, not a universal speedup.
The larger gains appeared where the fixed split constrained capacity. On GPT-OSS-20B with 512 input tokens, 1,536 output tokens and 1,024 concurrent requests, unified memory ran about 1,000 requests simultaneously versus 618 with default separate pools. The post reports 14% higher throughput and time to first token of 6 seconds instead of 43 seconds.
For Qwen3.5-4B with 16K input tokens, 4,096 output tokens and concurrency 64, unified memory supported 32 running requests versus 22 and was 26% faster, according to the post.
These measurements suggest that the main opportunity is avoiding capacity stranded by a fixed partition. They do not establish equivalent gains for other models, hardware or traffic patterns, and the supplied evidence does not include independent replication.
Compatibility and remaining limits
The post lists support for overlap scheduling, Radix cache, HiCache, prefill–decode disaggregation, selected speculative-decoding configurations and several parallelism modes. Those features are not freely interchangeable: prefill–decode disaggregation requires Mooncake and cannot be combined with pipeline parallelism, speculative decoding or decode context parallelism. HiCache cannot be combined with EAGLE or EAGLE3.
Full-attention-only models, MLA models with sliding-window layers and DeepSeek-V4 are not currently supported. Priority preemption is disabled, and --max-running-requests still reserves a fixed number of request slots. The post also warns that admission assumes recurrent checkpoints advance; without an available tracking or replacement state slot, a request can retain more window rows than its admission estimate allowed.
For operators, this makes unified memory a workload-specific experimental option rather than a general replacement for every SGLang deployment. Its potential advantage is less partition tuning and better use of existing capacity, but adoption still requires checking model compatibility, feature combinations and actual serving behavior.
SGLang’s Experimental Unified Memory Shares GPU Capacity Across Hybrid Model States
SGLang’s experimental unified memory lets hybrid models share GPU capacity across KV caches and recurrent state.
 Routing Brief admin